in this blog, i will try to explain how i built a 3-tier search autocomplete system using the google books ngram dataset. the dataset is not an actual search queries dataset, so i will also explain how i curated it.
we will be building around the problem of designing top k most searched queries.
Full Code on my github
Design Decisions
- we will only be having an english corpus, and we will use unicode code points.
- our dataset will contain at max 10 mil queries (no reasoning behind this, just a random number)
Dataset
Format
every dataset will be formatted into
phrase\tfreq
where phrase is the actual phrase and freq is the number of times that phrase is searched
- i have tried this with multiple datasets, but the versions of my dataset are roughly 2
V1 [AOL QUERIES]
- I have used aol_queries
- you can read about the dataset here - https://en.wikipedia.org/wiki/AOL_search_log_release
- please note that the dataset is not filtered and has nsfw words. i haven’t filtered it either, and used it as-is. please use it at your discretion
- one good thing about this dataset is that i don’t need to format it into
phrase\tfreqformat, so we can use it directly
sample records in the dataset:
google	68513
mapquest	37252
google.com	29023
ebay	28715
yahoo.com	27669
yahoo	26930
myspace.com	22000
internet	21996
map quest	13366
myspace	13005
there are exactly 433614 records in this dataset. this should be comfortably doable on my machine (16GB RAM)
V2 [GOOGLE BOOKS NGRAM DATASET]
- now this one is a bit tricky
- i have downloaded all these from - https://storage.googleapis.com/books/ngrams/books/datasetsv3.html raw datasets:
googlebooks-eng-all-5gram-20090715-0
googlebooks-eng-all-5gram-20090715-248
googlebooks-eng-all-5gram-20090715-374
googlebooks-eng-all-5gram-20090715-795
googlebooks-eng-fiction-all-2gram-20090715-7
googlebooks-eng-fiction-all-2gram-20090715-24
googlebooks-eng-fiction-all-2gram-20090715-46
googlebooks-eng-fiction-all-2gram-20090715-51
googlebooks-eng-fiction-all-2gram-20090715-59
googlebooks-eng-fiction-all-3gram-20090715-7
googlebooks-eng-fiction-all-3gram-20090715-56
googlebooks-eng-fiction-all-3gram-20090715-156
googlebooks-eng-fiction-all-3gram-20090715-165
googlebooks-eng-fiction-all-3gram-20090715-168
googlebooks-eng-fiction-all-4gram-20090715-125
googlebooks-eng-fiction-all-4gram-20090715-154
googlebooks-eng-fiction-all-4gram-20090715-285
googlebooks-eng-fiction-all-4gram-20090715-307
googlebooks-eng-fiction-all-4gram-20090715-340
googlebooks-eng-fiction-all-4gram-20090715-352
googlebooks-eng-us-all-5gram-20090715-178
googlebooks-eng-us-all-5gram-20090715-344
googlebooks-eng-us-all-5gram-20090715-492
- they contain 2-gram, 3-gram, 4-gram, and 5-gram data
- i talked to deepseek and claude on how to convert these into my dataset format
phrase\tfreq - you can find the dataset cleaning and creation code here - github
- i also have another stage, performed a single time just before my seeding to mongo (will discuss what this is in the arch section) - but it goes something like this
- if the start of the phrase is not a letter (unicode) or a digit, we remove that phrase - as i observed, this helped me get rid of some illegible phrases starting with parentheses, etc. the existence of these makes sense in this dataset, because the dataset is derived from the google books ngram dataset
- we convert everything to lowercase - meaning our implementation is not case-sensitive
func normalize(s string) string {
	runes := []rune(strings.TrimSpace(s))
	i := 0
	for i < len(runes) {
		r := runes[i]

		if unicode.IsLetter(r) || unicode.IsDigit(r) {
			break
		}

		i++
	}
	return strings.ToLower(string(runes[i:]))
}
- let’s look at how we get to the clean
canonical_sorted.txt, which is in our desired dataset format for direct seeding
1. take the file generated by `preprocess_ngrams` code.eg: `ds.txt`
2. normalize each phrase in `ds.txt` and write to a file `normalized_ds.txt`
3. sort this file lexographically using linux `sort` command
4. aggregate the final file's duplicate queries and write to a final file: `canonical_sorted.txt`
sample from canonical_sorted.txt:
0 "" for the"	134862
0 ( no pain	166498
0 ) and after the	40000
0 ) and the corresponding	131572
0 ) can be	783047
0 ) cannot be	65536
0 ) does not satisfy	57135
0 ) for the first	108436
0 ) is equivalent to	100856
0 ) is positive definite	58893
we have around 9.6 mil records for our experiment
wc -l canonical_sorted.txt
# 9646759 canonical_sorted.txt
Architecture
I have iteratively implemented the architecture. i will split it into phases below
Phase 1: [BASIC TRIE - V1 Dataset]
In this phase, we will take the V1 dataset
❯ wc -l aol_queries.txt
# 433614 aol_queries.txt
and build a trie. before going into any implementation details, let’s look at how our trie is implemented in go
type Reco struct {
	Word string
	Freq int64
}


type Node struct {
	Val      rune
	Children map[rune]*Node
	IsWord   bool
	Freq     int64
	Top      []Reco
}
type Trie struct {
	Root       *Node
	K          int
	CacheDepth int
}
this is just like a basic tree, but a node can have many children. field specifics - what we store - is below
Node
- a node in our trie
Val: the character this node holds (redundant, no need to store, i just kept this because it gave me clarity while debugging)Children: the children of this nodeIsWord: will be true if a word is formed until the nodeFreq: the frequency of this word/phrase from our datasetTop: we cache the top-K most occurring words at this node (using theRecotype, which has the word/phrase and its freq). this is an optimization
Trie
Root: also a Node withVal=""K: for this phase 1 implementation, we initialize this trie with a number K, the number of suggestions/auto-completes to be returned per queryCacheDepth: see point 6 fromNode, we limit the depth past which noTopis populated at the node in the trie, so we only cache the shallow nodes. this can be set to the numberx, wherexis the average number of characters a user types before selecting a suggestion. this helps us save memory when all the queries are answered from an in-memory trie (or prefix-index hash map)
Building the Trie
func BuildTrie(ipfile string) *Trie {
	trie := NewTrie()
	file, err := os.Open(ipfile)
	if err != nil {
		panic("error opening file,cannot build trie")
	}
	defer file.Close()
	scanner := bufio.NewScanner(file)
	for scanner.Scan() {

		line := strings.TrimSpace(scanner.Text())
		phrase, freq, ok := ParseLine(line)
		if ok {
			trie.Insert(phrase, freq)
		}

	}
	if err := scanner.Err(); err != nil {
		panic(fmt.Sprintf("failed build trie..%s", err.Error()))
	}
	return trie
}
- we traverse our dataset line by line, parsing each line to give us a phrase and a frequency our insert is also simple
func (t *Trie) Insert(s string, freq int64) {
	// insert and return the freq of the word
	node := t.Root
	for _, x := range s {
		if node.Children == nil {
			// if the node doesnot have children -lets initialize here
			node.Children = make(map[rune]*Node)
		}
		nextnode, ok := node.Children[x]
		if !ok {
			// add new
			nextnode = NewNode()
			nextnode.Val = x
			node.Children[x] = nextnode
		}
		node = nextnode
	}
	node.IsWord = true
	node.Freq = freq
}
with this we can easily search our trie using
func (t *Trie) Search(s string) (bool, bool, int64, *Node) {
	// search for a string in the trie
	// first bool -> if the string exists
	// second bool -> if the string is a word or not
	node := t.Root
	for _, x := range s {
		nextnode, ok := node.Children[x]
		if !ok {
			return false, false, 0, nil
		}
		node = nextnode
	}
	return true, node.IsWord, node.Freq, node
}
you can find the whole trie implementation here: github_trie.
Phase 2: [PREFIX INDEX HASH MAP - V1 Dataset]
- what we will include here is a simple hashmap. every prefix that can be formed while traversing the trie will be a
keyfor the hashmap. the value will be what we want to return when that prefix is typed (the search query), i.e., a list of top-K words.
type PrefixIndex map[string][]Reco

func NewPrefixIndex() PrefixIndex {
	return PrefixIndex{}
}
that’s it, our prefix index is that simple. we can easily build the prefix index from our trie using
func (t *Trie) walkForIndex(node *Node, prefix string, pi PrefixIndex) []Reco {
	cands := make([][]Reco, 0, len(node.Children)+1)
	if node.IsWord {
		cands = append(cands, []Reco{{Word: prefix, Freq: node.Freq}})
	}
	for key, child := range node.Children {
		cands = append(cands, t.walkForIndex(child, prefix+string(key), pi))
	}
	var top []Reco
	if len(cands) == 1 {
		top = cands[0] // already ≤ k meaning sorted
	} else if len(cands) > 1 {
		top = mergeTopK(cands, t.K)
	}
	pi[prefix] = top
	return top
}
notice the mergeTopK, we won’t re-calculate the top-K words for every node, instead we will perform a mergesort on the children’s top-k words
func mergeTopK(lists [][]Reco, k int) []Reco {
	h := &headHeap{}
	heap.Init(h)
	for _, l := range lists {
		if len(l) > 0 {
			heap.Push(h, head{l, 0})
		}
	}
	out := make([]Reco, 0, k)
	for h.Len() > 0 && len(out) < k {
		t := heap.Pop(h).(head) // take the largest current head
		out = append(out, t.list[t.idx])
		if t.idx+1 < len(t.list) { // that list still has elements?
			heap.Push(h, head{t.list, t.idx + 1}) // put the next one in the race
		}
	}
	return out
}
please find the heap definitions here: heap
searching and suggesting from our prefix index becomes extremely simple now. we don’t need to traverse anything to get the words to suggest, we just need to ask
func (pi PrefixIndex) Suggest(prefix string) []string {
	recos, ok := pi[prefix]
	if !ok {
		return nil
	}
	result := make([]string, 0, len(recos))
	for _, r := range recos {
		result = append(result, r.Word)
	}
	return result
}
but as our dataset becomes large, the number of prefixes we store increases very rapidly, and the performance of prefix-index might become even worse than using the optimized trie.
we will discuss these at length in the benchmarks section
Phase 3: [PREFIX INDEX HASH MAP - SAMPLE OF V2 Dataset (3 mil queries)]
i have worked on a sample of the V2 dataset (which has 9.6 mil records), specifically 3 mil queries, and put the trie and prefix-index hash map into memory to test the implementation. while it worked, it almost consumed all the RAM on my machine, which is understandable because of the nature of the data we store (many prefixes for a single phrase and their cache - the top-k words for each prefix)
so instead of working on that architecture, i have moved to a 3-tier serving architecture, explained below
Phase 4: [3-TIER SERVING]
The three tiers
- in-memory: prefix-index hash map of the n most frequently occurring prefixes (this should ideally be the n most searched queries, by the user, if implementing at a user level)
- redis: an lfu (least frequently used) cache of the m most frequently occurring prefixes - this should be the most searched in a real-world case
- db: mongodb collection containing all the required data of our 9.6 mil queries (we will have a robust seeder to seed the db)
obviously, m » n. we keep a very small subset of queries in memory and a considerable number of prefixes in redis.
MongoDB
- we seed our mongodb collection using our V2 dataset, similar to how we did in phases 1 and 2, where we seeded our implementation (trie / prefix-index) using the V1 dataset a record in our mongodb collection will look like
[
  {
    _id: ObjectId('6a9d1523913c9ac792f99562'),
    prefix: 't',
    top: [
      { word: 'to the', freq: Long('6720554310') },
      { word: 'to his', freq: Long('3844455287') },
      { word: 'to him', freq: Long('3484776154') },
      { word: 'the second', freq: Long('2717181751') },
      { word: 'the fact', freq: Long('2654935890') },
      { word: 'to that', freq: Long('2565932938') },
      { word: 'their', freq: Long('2328023435') },
      { word: 'this"', freq: Long('2323063288') },
      { word: 'tell you', freq: Long('2035448917') },
      { word: 'they are', freq: Long('1903789632') }
    ]
  }
]
you can easily draw parallels between our prefix-index hash map version and how we store our records in mongodb.
Seeder - Working
Definitions
our seeder is simple, recursive, and concurrent. let’s introduce 3 terms now
bucket: we will have a bucket for a prefixbucket metrics: the metrics that define the bucket
type BucketMetrics struct {
	Prefix           string
	Start            int64
	End              int64
	DistinctPrefixes int64
}
as you can see, we can identify which prefix a bucket belongs to using the Prefix field.
build: building a prefix-index hash map for each bucket. this is what we will execute concurrently (using goroutines to buildBucketMetricsfor each prefix)merge: merging the prefix-index we built into mongo (why merge instead of write/insert is explained below)
Why Recursive
- all the buckets, say all the phrases that start with a, b, c … z, do not contribute a similar number of prefixes. we will have a zipf-ish distribution
in our V2 dataset, look at the number of phrases that start with each character:
0 1294
1 35060
2 15410
3 9243
4 6518
5 5534
6 4372
7 3567
8 3480
9 2906
a 1081054
b 463271
c 481223
d 315831
e 264935
f 383647
g 185792
h 498113
i 605340
j 58559
k 55729
l 263414
m 404064
n 219218
o 611757
p 396727
q 23578
r 271870
s 692986
t 1420702
u 117667
v 83098
w 570821
x 2504
y 82832
z 4643
now the distinct prefixes contributed by each bucket will definitely be more, and if we proceed to build the prefix index for that bucket - where we need to store all the distinct prefixes and their top-k words - that definitely won’t fit in my system memory.
solution?: split each bucket until we can fit the prefix-index hash map built for that bucket in memory
but how do we split, and how do we estimate memory? enter our tiny experiment to find out whether we can proceed to build a bucket or split it further
Memory Estimation
you can find the end to end code here: mem_est
what we do is,
- take a sample from the V2 dataset (here i took 2 samples - 1 mil and 3 mil records)
goal: roughly estimate the bytes per prefix needed to store a prefix + its top-k words (the words here will be
WordandFreq, exactly what we use in our seeder).- this makes life easier, because we only need to calculate the distinct prefixes found in a bucket, multiply that by
bytesPerPrefix(an estimate we get from above), and check if it falls under our memory budget. if yes, build the prefix index for that bucket, else split further
below are the findings
1M-row dataset
| K | Distinct Prefixes | HeapAlloc | HeapInuse | Sys | Bytes / Prefix | Total Recos | Avg Recos / Prefix |
|---|---|---|---|---|---|---|---|
| 10 | 9,769,612 | 1,180.09 MB | 1,370.91 MB | 1,441.41 MB | 126.66 | 12,298,420 | 1.26 |
| 20 | 9,769,612 | 1,207.09 MB | 1,431.37 MB | 1,495.03 MB | 129.56 | 12,935,621 | 1.32 |
| 30 | 9,769,612 | 1,207.10 MB | 1,456.12 MB | 1,621.05 MB | 129.56 | 13,300,024 | 1.36 |
| 40 | 9,769,612 | 1,227.30 MB | 1,489.61 MB | 1,612.36 MB | 131.73 | 13,555,907 | 1.39 |
| 50 | 9,769,612 | 1,227.30 MB | 1,369.29 MB | 1,594.04 MB | 131.73 | 13,751,263 | 1.41 |
3M-row dataset
| K | Distinct Prefixes | HeapAlloc | HeapInuse | Sys | Bytes / Prefix | Total Recos | Avg Recos / Prefix |
|---|---|---|---|---|---|---|---|
| 10 | 26,369,788 | 2,931.63 MB | 3,585.84 MB | 3,746.15 MB | 116.57 | 33,943,880 | 1.29 |
| 20 | 26,369,788 | 3,013.93 MB | 3,573.92 MB | 3,716.96 MB | 119.85 | 35,879,985 | 1.36 |
| 30 | 26,369,788 | 3,013.91 MB | 3,623.60 MB | 3,771.91 MB | 119.85 | 36,991,688 | 1.40 |
| 40 | 26,369,788 | 3,075.59 MB | 3,744.35 MB | 3,900.10 MB | 122.30 | 37,769,573 | 1.43 |
| 50 | 26,369,788 | 3,075.47 MB | 3,838.52 MB | 4,011.54 MB | 122.29 | 38,369,444 | 1.46 |
we can roughly estimate that
bytesPerPrefixwill be 125-140. you can choose a number based on your machine’s config. if you want to be conservative, you can also choose 150
now, our bucket processing becomes increasingly simple
func processBucket(f *os.File, prefix string, start int64, end int64, collection *mongo.Collection,
	ctx context.Context) {
	scanResult := Scan(f, prefix, start, end)

	for _, child := range scanResult.Children {
		estimated := float64(child.DistinctPrefixes) * bytesPerPrefix

		if estimated <= memoryBudget {
			indexBuildJobs <- child
		} else {
			fmt.Printf(
				"SPLIT  %-10s prefixes=%d estimated=%.2f MB\n",
				child.Prefix,
				child.DistinctPrefixes,
				estimated/(1024*1024),
			)
			processBucket(
				f,
				child.Prefix,
				child.Start,
				child.End,
				collection,
				ctx,
			)
		}
	}
}
Concurrency
we will use go-routines to build our prefix-indexes for different prefixes. but spinning up a new go-routine for every child of a prefix defeats the purpose, and we cannot run our seeder locally like that. so we will have bounded concurrency here
channels
two buffered channels: 1 for processBucket to enqueue build jobs, and 1 for the index building workers to enqueue results
var (
	indexBuildJobs = make(chan BucketMetrics, 5)
	indexResults   = make(chan PI, 5)
)
workers
IndexBuildingWorkers
- consumes from
indexBuildJobsand sends ontoindexResults - 6 workers at anytime
- i used
const memoryBudget = 500 * MB, a memory budget of 500mb in our seeder. 6 index building workers running at any time ensure that the seeder executes comfortably, leaving headroom for the mongo process and other processes (i will detail these in a future blog) - with this config, my system memory usage never exceeds
10GB(i still need to explain why it is 10gb; i will write that in a future blog as learnings, sorry :) )
func IndexBuildingWorkers(path string, wg *sync.WaitGroup) {
	for range 6 {
		// there are 6 workers at any time - working on building prefix indexes
		// each's memory limit is capped to 500mb (done via estimated memory from the processBucket)
		wg.Go(func() {
			f, err := os.Open(path) // one handle per worker
			if err != nil {
				panic(err)
			}
			defer f.Close()
			for child := range indexBuildJobs {
				estimated := float64(child.DistinctPrefixes) * bytesPerPrefix
				fmt.Printf(
					"BUILD  %-10s prefixes=%d estimated=%.2f MB\n",
					child.Prefix,
					child.DistinctPrefixes,
					estimated/(1024*1024),
				)
				pi := buildPrefixIndex(f, child)
				fmt.Printf("QUEUEING - MERGE  %-10s prefixes=%d\n",
					child.Prefix,
					len(pi),
				)
				indexResults <- pi
			}

		})
	}
}
- the
buildPrefixIndexis similar to how we built our prefix-index in phase 2, but this time without a trie as an intermediate step
func buildPrefixIndex(f *os.File, child BucketMetrics) PI {
	_, err := f.Seek(child.Start, io.SeekStart)
	if err != nil {
		panic(err)
	}
	limited := io.LimitReader(f, child.End-child.Start)
	scanner := bufio.NewScanner(limited)
	pi := make(PI)
	for scanner.Scan() {
		phrase, freq, ok := trie.ParseLine(scanner.Text())
		if !ok {
			continue
		}
		runeList := []rune(phrase)
		for i := 1; i <= len(runeList); i++ {
			pref := string(runeList[:i])
			if pi[pref] == nil {
				hp := &trie.RecHeap{}
				heap.Init(hp)
				pi[pref] = hp
			}
			if pi[pref].Len() < k {
				heap.Push(pi[pref], trie.Reco{Word: phrase, Freq: freq})
			} else {
				if pi[pref].Top().Freq < freq {
					heap.Pop(pi[pref])
					heap.Push(pi[pref], trie.Reco{Word: phrase, Freq: freq})
				}
			}
		}
	}
	if scanner.Err() != nil {
		panic(scanner.Err())
	}
	return pi

}
MongoMergeWorker
func MongoMergeWorker(ctx context.Context, collection *mongo.Collection, done chan struct{}) {
	for pi := range indexResults {
		mergeIntoMongo(ctx, collection, pi)
	}
	close(done)
}
- our
mergeIntoMongofunction merges the existing doc for the prefix (if already present in our mongodb collection) with the incoming one, preserving the top-k words. it does this in batches ofbatchSize=1000. code here: mergeIntoMongo
Why only 1 MongoMergeWorker
consider this: you are processing with 2 mongo merge workers. one worker is building the prefix-index for bucket th, and the other is building the prefix-index for bucket to.
both will update the document for prefix=t (they will update its top-k words). without proper locking semantics they will race, causing lost updates and race conditions. this can be solved by partitioning our mongo instance and having different mongo merge workers update different shards. i haven’t done that in this architecture, so i will include it in the next steps.
Scan
given a prefix, our Scan function scans the file (our V2 dataset) to find the children bucket boundaries and returns a ScanResult which processBucket can use
type ScanResult struct {
	Children []BucketMetrics
}
func Scan(f *os.File, prefix string, start int64, end int64) ScanResult {
	_, err := f.Seek(start, io.SeekStart)
	if err != nil {
		panic(err)
	}
	limited := io.LimitReader(f, end-start)
	scanner := bufio.NewScanner(limited)
	prefixRunes := []rune(prefix)
	prefixLen := len(prefixRunes)
	var children []BucketMetrics
	var currentChild string
	var childStart int64
	var childDP int64
	childDP = 1
	prevPhrase := ""
	var offset int64
	for scanner.Scan() {
		line := scanner.Text()
		//advance offset
		lineSize := int64(len(line) + 1)
		offset += lineSize
		phrase, _, ok := trie.ParseLine(line)
		if !ok {
			continue
		}
		runes := []rune(phrase)
		// processing children, if have no extra text after the prefix for the current prefix, lets continue
		if len(runes) <= prefixLen {
			continue
		}
		// if the prefix of the current phrase doesnot equal to prefix
		// continue - ideally this should not happend if we have built our canonical sorted dataset correclty - safety check
		if prefixLen > 0 && !strings.HasPrefix(phrase, prefix) {
			panic(fmt.Sprintf(
				"phrase %q outside prefix bucket %q",
				phrase,
				prefix,
			))
		}
		// child= prefix + next rune.
		child := string(runes[:prefixLen+1])
		// new child bucket
		// but here the currentCHild is techncially previousChild isnt it?
		if child != currentChild {
			// complete prev child
			if currentChild != "" {
				children = append(children, BucketMetrics{
					Prefix:           currentChild,
					Start:            childStart,
					End:              start + offset - lineSize,
					DistinctPrefixes: childDP,
				})
			}
			//new child
			currentChild = child
			// since we already increased the offset, we need to substract the lineSize from offset to get the start of the
			// new child
			childStart = start + offset - lineSize
			childDP = 0
			// reset lcp for every child.
			prevPhrase = ""
		}
		// count new distinct prefixes
		childDP += int64(
			len(runes) - max(prefixLen+1, lcp(phrase, prevPhrase)),
		)
		prevPhrase = phrase
	}
	if err := scanner.Err(); err != nil {
		panic(err)
	}
	//close final child
	if currentChild != "" {
		children = append(children, BucketMetrics{
			Prefix:           currentChild,
			Start:            childStart,
			End:              start + offset,
			DistinctPrefixes: childDP,
		})
	}

	return ScanResult{
		Children: children,
	}
}
Buckets Processed
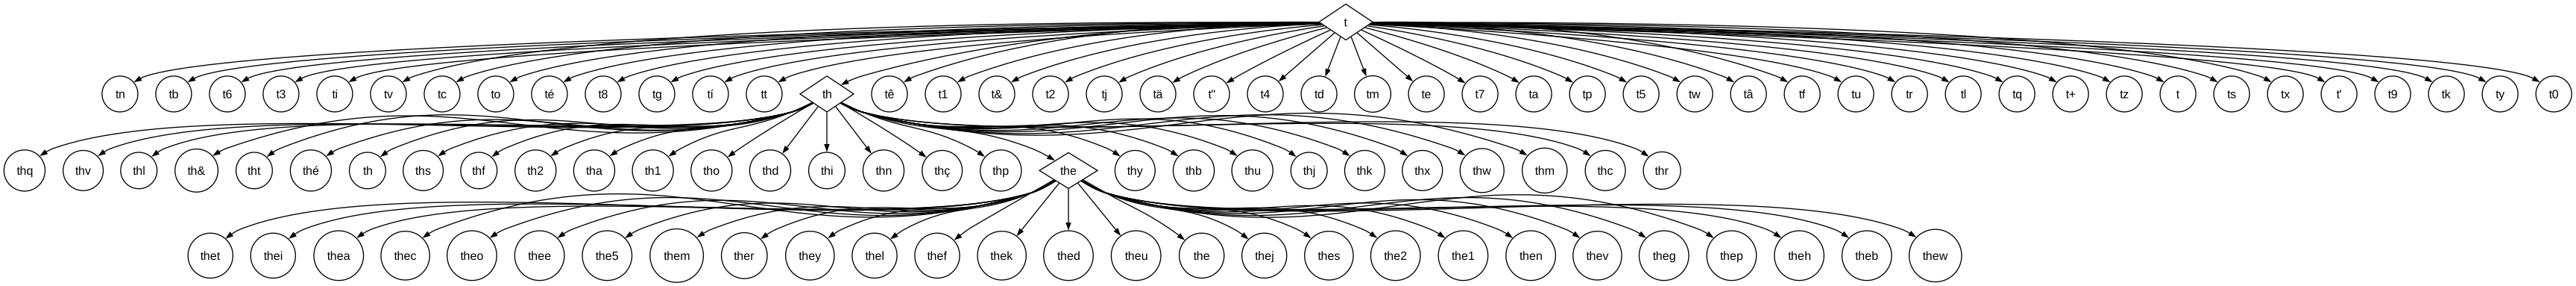
I have tried to visualize part of the bucket recursive splitting work using graphviz. hope the images below make sense
- only the buckets shown in this gallery are split and processed; all the rest are processed in one go, because they fit the memory estimate
- check out the
tbucket for a detailed split




Benchmarks
[will populate] - you can have a peek at: https://github.com/arjun118/system_design_implementations/blob/main/search_autocomplete/benchmarks.md
please note that the benchmarks are only for phases 1 and 2. i will update this section with all the phases
Request flow
s.memory.Get prefix"} %% L1 Memory Hit CheckMem -- "Hit: ok == true" --> RetMem["Set source = in-memory"] %% L2 Redis CheckMem -- "Miss" --> CheckRedis{"2. Redis Cache?
s.redis.Get prefix"} CheckRedis -- "Hit: ok == true" --> RetRedis["Set source = cache"] %% L3 MongoDB CheckRedis -- "Miss" --> CheckDB["3. MongoDB Store
s.mongo.Get prefix"] CheckDB --> DBStatus{"Result?"} DBStatus -- "Error / Not Found" --> RetErr["Return nil"] DBStatus -- "Success" --> RetDB["Set source = db"] %% Async write RetDB -.-> Async["Async Goroutine
s.redis.Set prefix, result"] Async -.-> RedisNode[(Redis)] %% Final formatting RetMem --> Format["Extract []string from []Reco"] RetRedis --> Format RetDB --> Format Format --> Done([Return suggestions, source]) classDef cache fill:#e1f5fe,stroke:#0288d1,stroke-width:1px; classDef db fill:#e8f5e9,stroke:#388e3c,stroke-width:1px; class CheckMem,CheckRedis cache; class CheckDB,DBStatus db;
Demo
Next Steps
- query logging + adaptive learning (Mongo/Redis)
- sharding and parallelizing seeding, and its impact on reads
- working on an atomic replace architecture where a worker keeps the in-memory state and cache in sync, updating every x mins or something like that